Over the past two days, my LibTV account still had more than 45,000 credits, with only two days remaining on limited-time benefits for several models.
Using up the credits would be easy. Copy a prompt, click through a few models, and wait for the videos. But I wanted those credits to buy something I could use again later: a few pieces of work, a real comparison, and some experience I could share.
So I used six video models for two rounds of advertising experiments.
Let me be clear at the outset. I am not particularly proficient with any of these six models, and generated only once with each. The impressions below apply only to this prompt, this platform entry point, and this particular draw. Change the situation, and the results could easily reshuffle.
That is probably part of why I want to record it.
Running the same prompt six times
In the first round, I used exactly the same prompt for all six models.
The task was a fifteen-second advertisement for a fictional luxury perfume. The product was called LUMINA, and the setting was a hotel on a rainy night. A woman in a black evening dress walks from the window to a stone counter, picks up a transparent perfume bottle, and the ad ends on a still product shot.
All six models used 16:9 landscape, fifteen seconds, and text-only generation, with neither a character reference image nor a product image. Prompt optimization was switched off, and each model ran once.
The models were Seedance 2.5, Seedance 2.0 Fast VIP, Seedance 2.0 Mini, Wan 3.0, HappyHorse 1.1, and MiniMax H3 Max.
All six first-round test videos can be watched in the original WeChat article.
Put side by side, the differences were immediately visible.
Some models were good at creating the atmosphere of a perfume advertisement. Rainy night, glass, highlights, black dress, and slow motion: all there, and at first glance quite convincing. Some handled lettering on the bottle more steadily, even preserving LUMINA in full. Some made beautiful product shots, but as soon as the character picked up the bottle, its proportions and cap began quietly changing.
The differences in the characters were even clearer.
My prompt specified a twenty-eight-year-old East Asian woman, but Seedance 2.5 generated someone who looked considerably more mature. To me, she even looked a little like a particular Chinese American Hollywood actor. That is highly subjective, but it directly affects whether I would be willing to deliver the image to a client.
In two other videos, the character stood by the window and exhaled a conspicuous white cloud. The rainy hotel atmosphere was there, but the films never explained why the room was cold enough for breath to show. The models may have been trying to understand “breathing faintly visible” and followed it a little too diligently.
Another model turned restrained emotion into an advertising smile. It was hard to call the image unattractive; the character simply was not following the state described in the prompt.
If I compared only the final frame, many models looked good. As the videos actually played, differences gradually emerged in the character’s age, hand movements, bottle shape, liquid level, and emotional changes.
The first round confirmed something for me. One shared prompt can reveal basic differences, but hardly determines what a model is really suited to. Making everyone take the same examination is fair, but the subject may not be everyone’s strongest.
I gave each of them a different task
For the second round, I used public information and creators’ examples to choose a setting in which each of the six models seemed more likely to perform well.
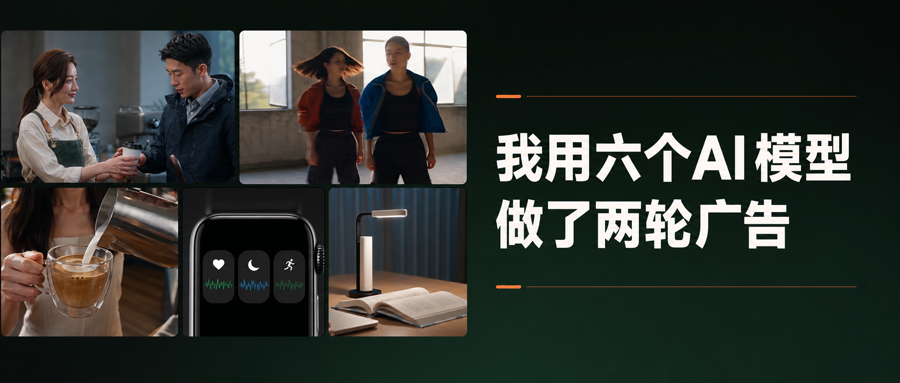
Seedance 2.5 made a thirty-second urban women’s fashion film with a character reference image. Wan 3.0 made a two-person café scene. MiniMax H3 Max made a smartwatch motion-graphics ad. HappyHorse 1.1 made a two-person street dance. Seedance 2.0 Fast VIP made a coffee sequence in one continuous shot. Seedance 2.0 Mini made a feed ad for a magnetic desk lamp.
This round was no longer trying to be fair. I wanted to see whether placing a model in a suitable role brought the result closer to usable.
Four videos from the second round are included in the original WeChat article. The other two could not be included because of the limit on videos in a single article.
After adding a character reference image for Seedance 2.5, the age issue from the previous round improved noticeably. Over thirty seconds, identity and overall presence remained relatively stable, with continuous changes between a hotel room, corridor, and exterior spaces. A reference image helped an advertisement featuring a realistic person more directly than piling further appearance adjectives into the prompt.
Wan 3.0’s two-person café scene was well realized. The relationship between barista and customer was clear, and positions, cups, and dialogue connected coherently. It already had the basic form of a short-drama advertisement. This was still only one result, but for now I am willing to try it first for two-person interaction and native dialogue scenes.
HappyHorse 1.1’s two dancers also surprised me. Blue and orange clothing clearly distinguished them, their movements had force, and the spatial relationships in the shot largely held up. Complex bodily contact still needs frame-by-frame checking, but at least the result makes me want to keep testing movement and dance.
MiniMax H3 Max’s watch ad looked like a complete motion-graphics short. PULSE ONE, HEART 72, SLEEP 86, and RUN 5.2 KM were mostly readable, and the black and electric-blue visual style was fairly consistent.
The price of one generation is only a small part of the bill
After the two rounds, I cared more and more about “the chance of a usable result in one generation.”
Credit prices on model pages are easy to compare. Delivering an actual advertisement also requires accounting for character references, product images, prompt revisions, retries, post-production fixes, and human checks.
H3 produced the wrong aspect ratio on its first attempt and needed another run. Mini’s desk lamp would also require rewriting the task or regenerating before delivery. Seedance 2.5 cost more, but its character reference image reduced age drift. There is no simple answer here.
If a cheap model meets the need in one attempt, of course it is good value. If an expensive model needs fewer retries, it may end up costing less. Price needs to be considered alongside the task.
There is also a very plain business question: making a more expensive video does not automatically make the product sell better.
Many feed videos only need to explain one benefit clearly. If viewers understand it, the image has no obvious errors, and the cost is low, it may be enough. A premium brand film needs greater care with people, materials, lighting, and rhythm, so the budget naturally rises.
Clients buy communication results and a specific use. Few pay specifically because “a more expensive model was used.”
Can viewers understand what it is saying? Could errors in the image harm the product or brand? Once the requirement is met, are the credit, retry, and post-production costs appropriate?
Answer those three questions before discussing which model is stronger, and the judgment becomes much steadier.
This is not a model ranking
I am still learning to use these models too. The prompt, reference material, platform entry point, and randomness all change the result. Creators who study video models over the long term can surely use each one more deeply than I can.
I would rather view these two rounds as a beginner’s record from the scene.
Round one showed me how the same prompt becomes six different interpretations in different models. Round two showed me how strengths and weaknesses emerge together when models enter different situations.
I did not find a champion that could handle every advertisement.
What I did keep was a method I can use again: test basic capabilities with a shared task, then test practical usability with tasks suited to each model’s strengths. Generate only once each time, keep the failures, and do not rush to hide problems through repeated retries. Once there are more samples, adjust the judgment.
For someone beginning to make AI videos, this may be more useful than memorizing a model ranking.
The next time a real request arrives, you do not have to begin by asking which model is most impressive. First look at what the client needs to express and which details absolutely cannot be wrong. Decide where to spend the credits last.
I still have quite a few credits left.
This time, I think I know how to spend them.
The views, experiences, and final judgments in this article are the author’s. AI assisted with organizing the text and generating illustrations.
What did this bring to mind?
Share a memory, a different view, or a thought you would like to continue. No account is needed. Comments appear after review; readers’ words remain in their original language.
Conversation
Loading comments…